ENEnglish
 LTLietuviškai
 DEDeutsch
 FRFrançais
 RUРусский
 ESEspañol
 PLPolski
 ITItaliano
 UKУкраїнська
 CSČeština
 PTPortuguês
 JA日本語
 LVLatviešu valoda
 ETEesti
 HUMagyar
 IDBahasa Indonesia
 TRTürkçe
 HIहिन्दी
 ELΕλληνικά
 ARالعربية
 THไทย
 VITiếng Việt
 RORomână
 MSBahasa Melayu
 BNবাংলা
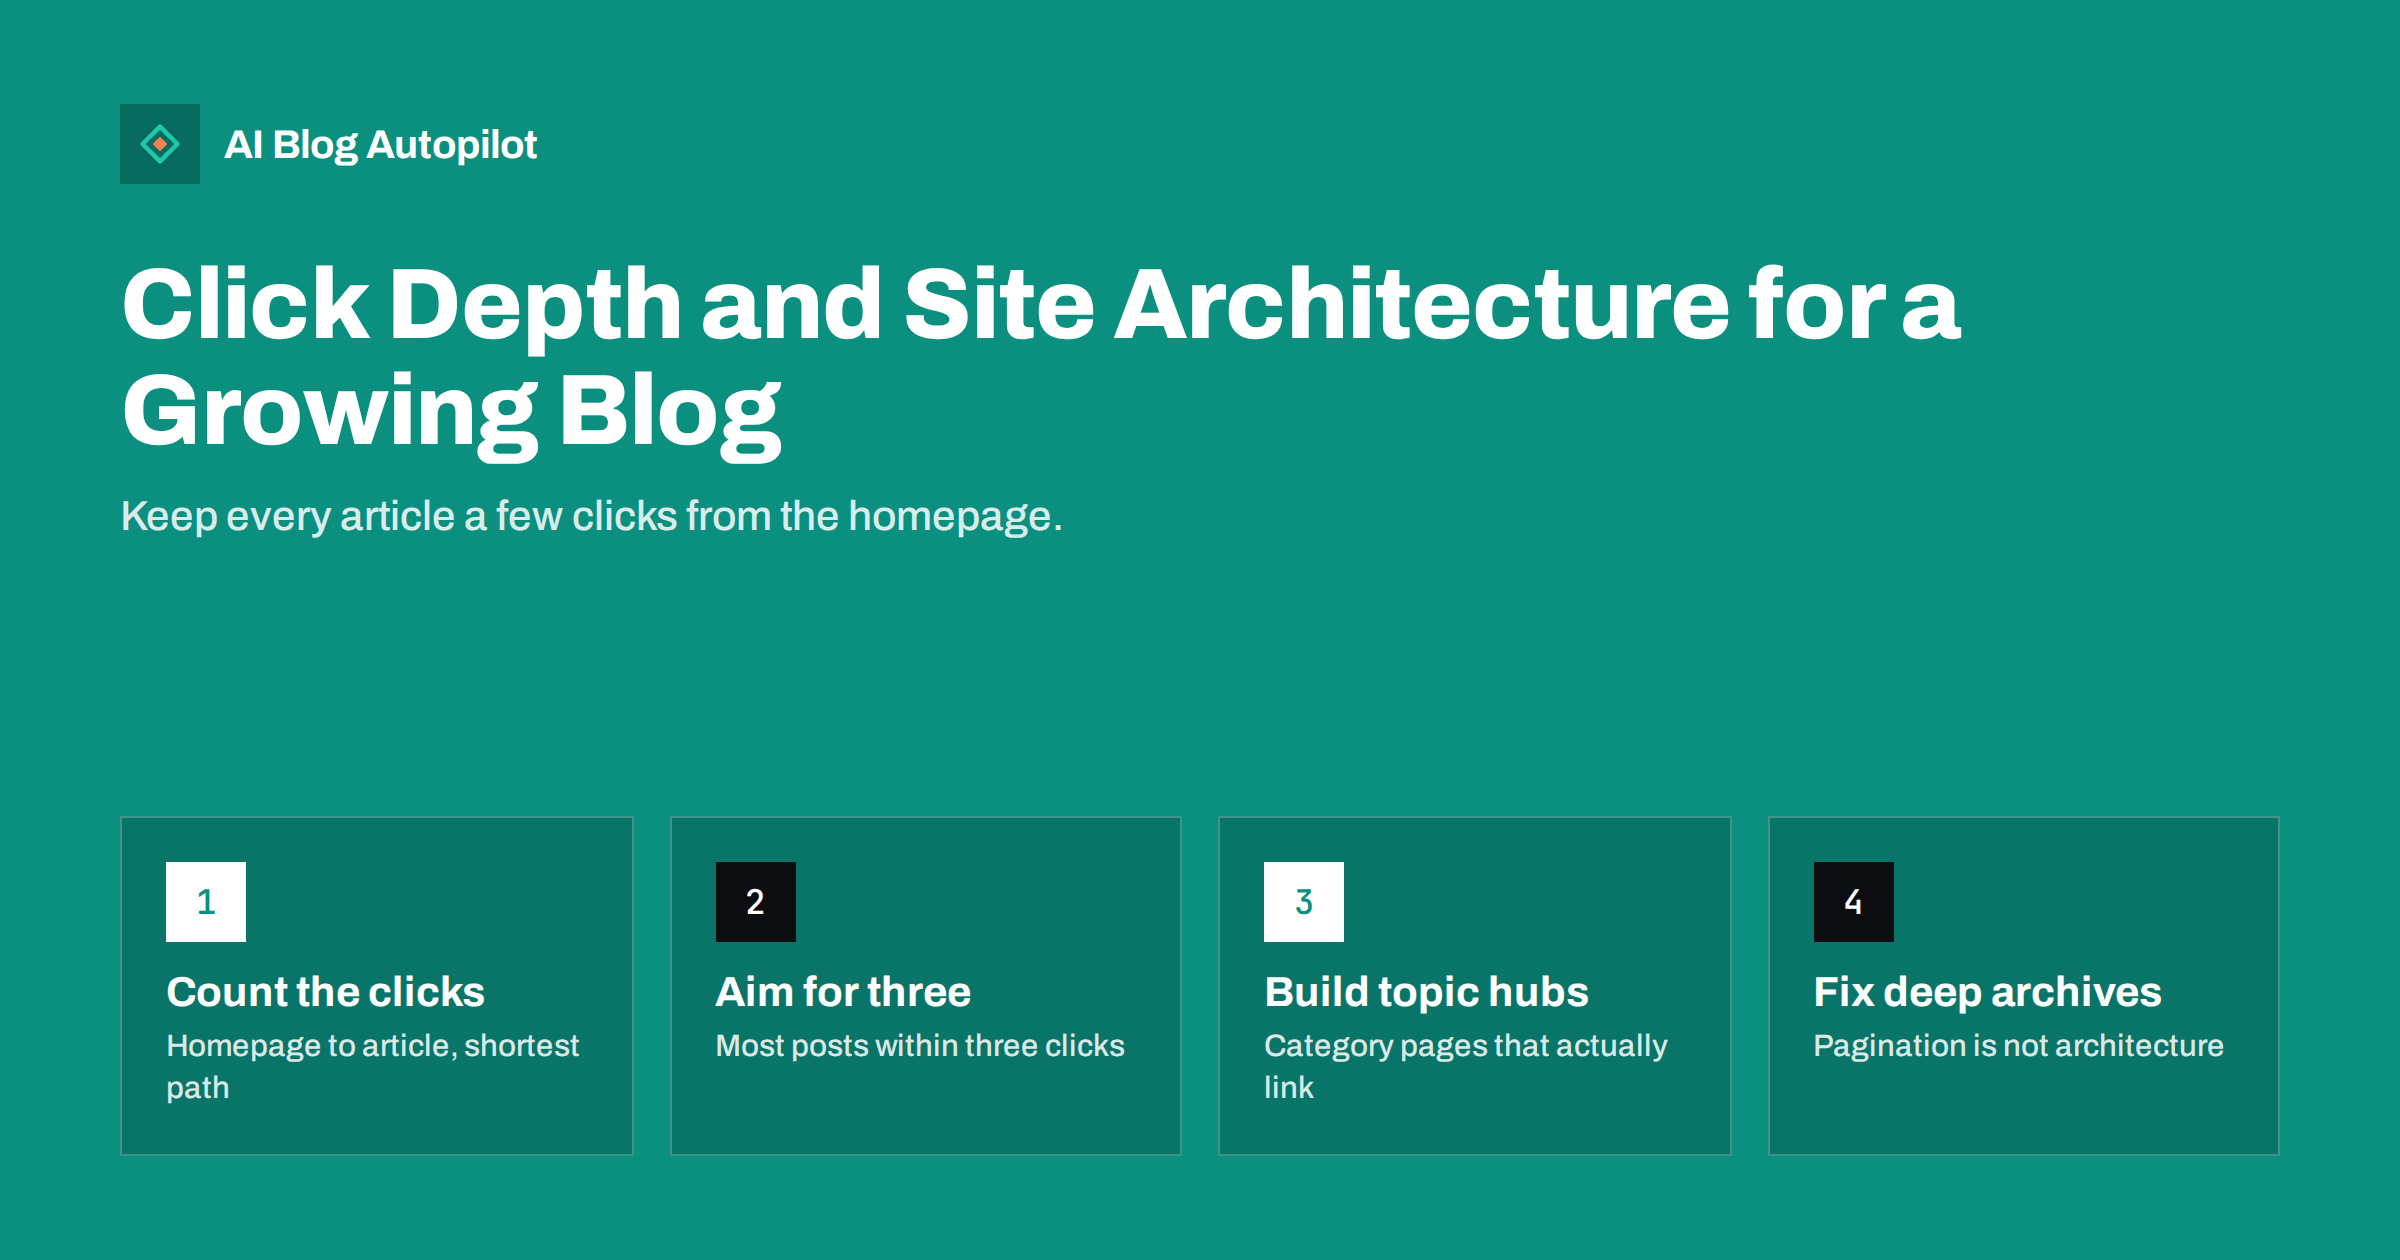
Short answer: click depth is the number of clicks it takes to reach a page from the homepage by the shortest path. On a blog, posts that sit many clicks deep are usually crawled less often and receive less internal link value, so they tend to be found and refreshed more slowly. A good working target is to keep important articles within about three clicks, using topic hubs, contextual links and sensible archives rather than long chains of paginated pages.
Most blogs start with perfect architecture by accident. With twenty posts, everything is linked from the homepage or the first archive page. The trouble begins at a few hundred posts, when new articles push older ones down the paginated blog list until a good guide from two years ago is twelve pages deep and reachable only through “Older posts” links. Nothing is technically broken, yet those articles slowly fade. This guide explains how to measure click depth, why it matters, and how to fix it without redesigning the whole site.
What click depth means
Click depth, sometimes called crawl depth or page depth, counts the minimum number of links a visitor or crawler has to follow from the homepage to reach a page. The homepage is depth 0. A category page linked from the main menu is depth 1. An article linked from that category page is depth 2. If the article only appears on page 9 of the category, and each archive page links only to the next one, the article may be at depth 10 or more.
Two details matter:
- It is the shortest path that counts. One good link from a well-linked page can pull an article from depth 11 to depth 2 instantly.
- It is not the same as URL structure. A URL like
/blog/seo/technical/canonical-tags/looks deep, but if the homepage links to it directly, its click depth is 1. Folder levels in a URL and click depth are separate things.
Why click depth matters for SEO
Search engines discover pages mainly by following links, and they use internal links as one of many signals about which pages a site considers important. Google’s own documentation recommends that every page you care about is reachable through at least one crawlable link from somewhere else on your site, which you can read about in its guidance on crawlable links.
In practice, deep pages tend to suffer in three ways:
- Slower discovery and recrawling. A crawler reaches pages near the homepage often. Pages many hops away are visited less frequently, so updates to old posts can take longer to be noticed.
- Less internal link value. Pages with few internal links pointing at them, all from weak archive pages, generally receive less of the authority that flows through a site’s links.
- Fewer human visits. Readers rarely click through ten archive pages. If they cannot find an article through navigation or related links, it effectively does not exist for them either.
Click depth is not a ranking factor you can tune to a magic number. It is a symptom. A shallow site usually has good navigation and internal linking; a deep site usually has neither. Fix the structure and the depth numbers improve as a side effect.
How to measure click depth on your blog
You need a crawler that starts at the homepage and records the shortest path to each URL. Most desktop SEO crawlers report this as “crawl depth” or “level”. The process is the same in any of them:
- Crawl the site starting from the homepage, following only internal links that a search engine can follow. Exclude URLs blocked by robots.txt and pages marked noindex if you want a clean view of indexable content.
- Export the list of article URLs with their depth.
- Group by depth and count how many posts sit at each level.
- Sort your most valuable articles (by traffic, conversions or business importance) and check their depth individually.
Then compare the crawl with your sitemap. Any article in the XML sitemap that the crawler did not reach at all is an orphan page: it has no internal links pointing to it. Orphans are the extreme case of click-depth trouble and should be fixed first.
A healthy blog of a few hundred posts usually shows most articles at depth 2 or 3, a small tail at 4, and almost nothing deeper. If the chart shows a long tail at depths 6 to 15, pagination is doing the linking work that your structure should be doing.
What causes deep pages on a blog
The same few causes appear on almost every blog that grows past its first year:
- Chronological pagination as the only path. The blog index shows ten posts per page, and older posts drift further back every time something new is published.
- Thin category pages. Categories exist but are not in the menu, or they paginate the same way as the main index.
- Too many tags with one or two posts. Tag archives can help discovery, but hundreds of near-empty tag pages add crawl paths without shortening the route to anything important.
- No contextual links. Articles are published without linking to related older posts, and older posts are never edited to link to newer ones.
- “Load more” buttons or infinite scroll that rely on JavaScript. If older posts only appear after a script runs and there is no plain paginated link, crawlers may not see them through that path at all.
Practical ways to make a blog shallower
You do not need to restructure URLs to reduce click depth. Most fixes are about adding links in the right places.
1. Turn categories into real topic hubs
Keep a small number of categories, five to ten for most blogs, and link to each from the main navigation. Make each category page useful: a short introduction, the most important articles pinned at the top, and then the rest of the list. A visitor landing there should see the best of the topic, not just the latest post.
2. Build pillar pages for your main topics
A pillar or guide page links to every important article in a cluster, grouped by subtopic. Linked from the menu or homepage, it puts dozens of articles at depth 2 in one move. It also helps readers, who get a curated route through a subject instead of a date-ordered list.
3. Add contextual links in every new article
Each new post should link to two to four older posts where it naturally makes sense, and each important older post should be edited occasionally to link forward to newer ones. Contextual links from relevant text are the most valuable internal links you can create.
4. Use related-posts sections carefully
Related-post blocks at the end of articles create many extra paths. Choose a method that picks genuinely related posts by topic rather than random or most-recent ones, so that older articles keep appearing next to new content.
5. Improve pagination rather than removing it
Keep paginated archives crawlable with normal links. Numbered pagination that shows several page numbers, and links to the first and last pages, shortens paths compared with a single “Next” link. Showing more posts per archive page also helps, as long as page speed stays acceptable.
6. Add an HTML sitemap or archive index
An HTML sitemap page that lists all articles by category, linked from the footer, puts every post within two clicks of the homepage. It is not glamorous, but it is a reliable safety net for discovery.
Flat versus deep: finding the right balance
Flattening a site does not mean linking every article from the homepage. A homepage with five hundred links dilutes attention and helps nobody. The goal is a clear hierarchy where each level is meaningful.
| Structure | Typical depth of older posts | Main risk |
|---|---|---|
| Chronological index only | Grows with every new post | Older articles get buried |
| Categories in menu, paginated | Moderate, depends on category size | Large categories still get deep |
| Categories plus pillar pages and contextual links | Mostly 2 to 3 | Needs ongoing link maintenance |
| Everything linked from homepage | 1 | No hierarchy, diluted signals, poor usability |
The third row is the target for most content sites: a shallow but organised structure where the important pages are close to the top and every page belongs to a clear topic.
A quick click depth checklist
- Crawl the site and record the depth of every indexable article.
- Fix orphan pages first by linking to them from relevant articles and hubs.
- List articles deeper than depth 4 and give each at least one contextual link from a well-linked page.
- Make sure categories are linked from the main navigation and their pages show key articles first.
- Create or update pillar pages for your three to five biggest topics.
- Check that pagination uses plain crawlable links, not only a JavaScript “load more” button.
- Add an HTML sitemap or archive page in the footer if you do not have one.
- Re-crawl after changes and compare the depth distribution.
How AI Blog Autopilot helps
AI Blog Autopilot writes and publishes full SEO articles to a WordPress blog on a steady schedule, with FAQ sections, tags and SEO meta included. Because it plans articles around your chosen topics, new posts naturally build up topic clusters instead of a random stream, which makes hubs and pillar pages easier to maintain. You still decide on your site’s navigation and category structure; the steady output simply gives that structure more relevant content to organise. You can see how it works on the AI Blog Autopilot homepage.
Related reading
- Orphan Pages: Finding Blog Posts Nothing Links To
- Breadcrumbs and Navigation for a Growing Blog
- Pagination and Archive Pages: SEO for Blog Listings
- Content Clusters and Pillar Pages, Explained Simply
The bottom line
Click depth tells you how hard it is to reach an article from your homepage. On growing blogs, chronological pagination quietly pushes older posts deeper every week. Measure depth with a crawler, fix orphans first, and then shorten paths with topic hubs, pillar pages, contextual links and an HTML sitemap. Aim for most important posts within about three clicks, and re-check after every major batch of new content.
DUK
What is a good click depth for blog posts?
For most blogs, keeping important articles within about three clicks of the homepage is a sensible target. Depth 4 is acceptable for less important posts. Anything deeper usually means the page relies only on pagination or has too few internal links.
Is click depth the same as URL depth?
No. URL depth is the number of folders in the address, while click depth is the number of links you follow from the homepage. A page with a long URL can be one click away if the homepage links to it directly.
Does reducing click depth improve rankings directly?
Not on its own. Shallower pages are typically discovered and recrawled more easily and receive more internal link value, which can support rankings. The content still has to match search intent and be useful.
Should I link every post from my homepage to make the site flat?
No. A homepage with hundreds of links is hard to use and spreads internal signals thinly. Use categories, pillar pages and contextual links to create a clear hierarchy where important pages sit two or three clicks deep.
Do tag pages help reduce click depth?
They can, if tags are few and each groups several related posts. Hundreds of tags with one or two posts each add crawl paths without making important content easier to reach. Keep tags meaningful and link the main ones from relevant places.